chenziqi-t
Hidden LLM API Hidden Fees Exposed: How RouteAI Eliminates Extra Charges in 2026
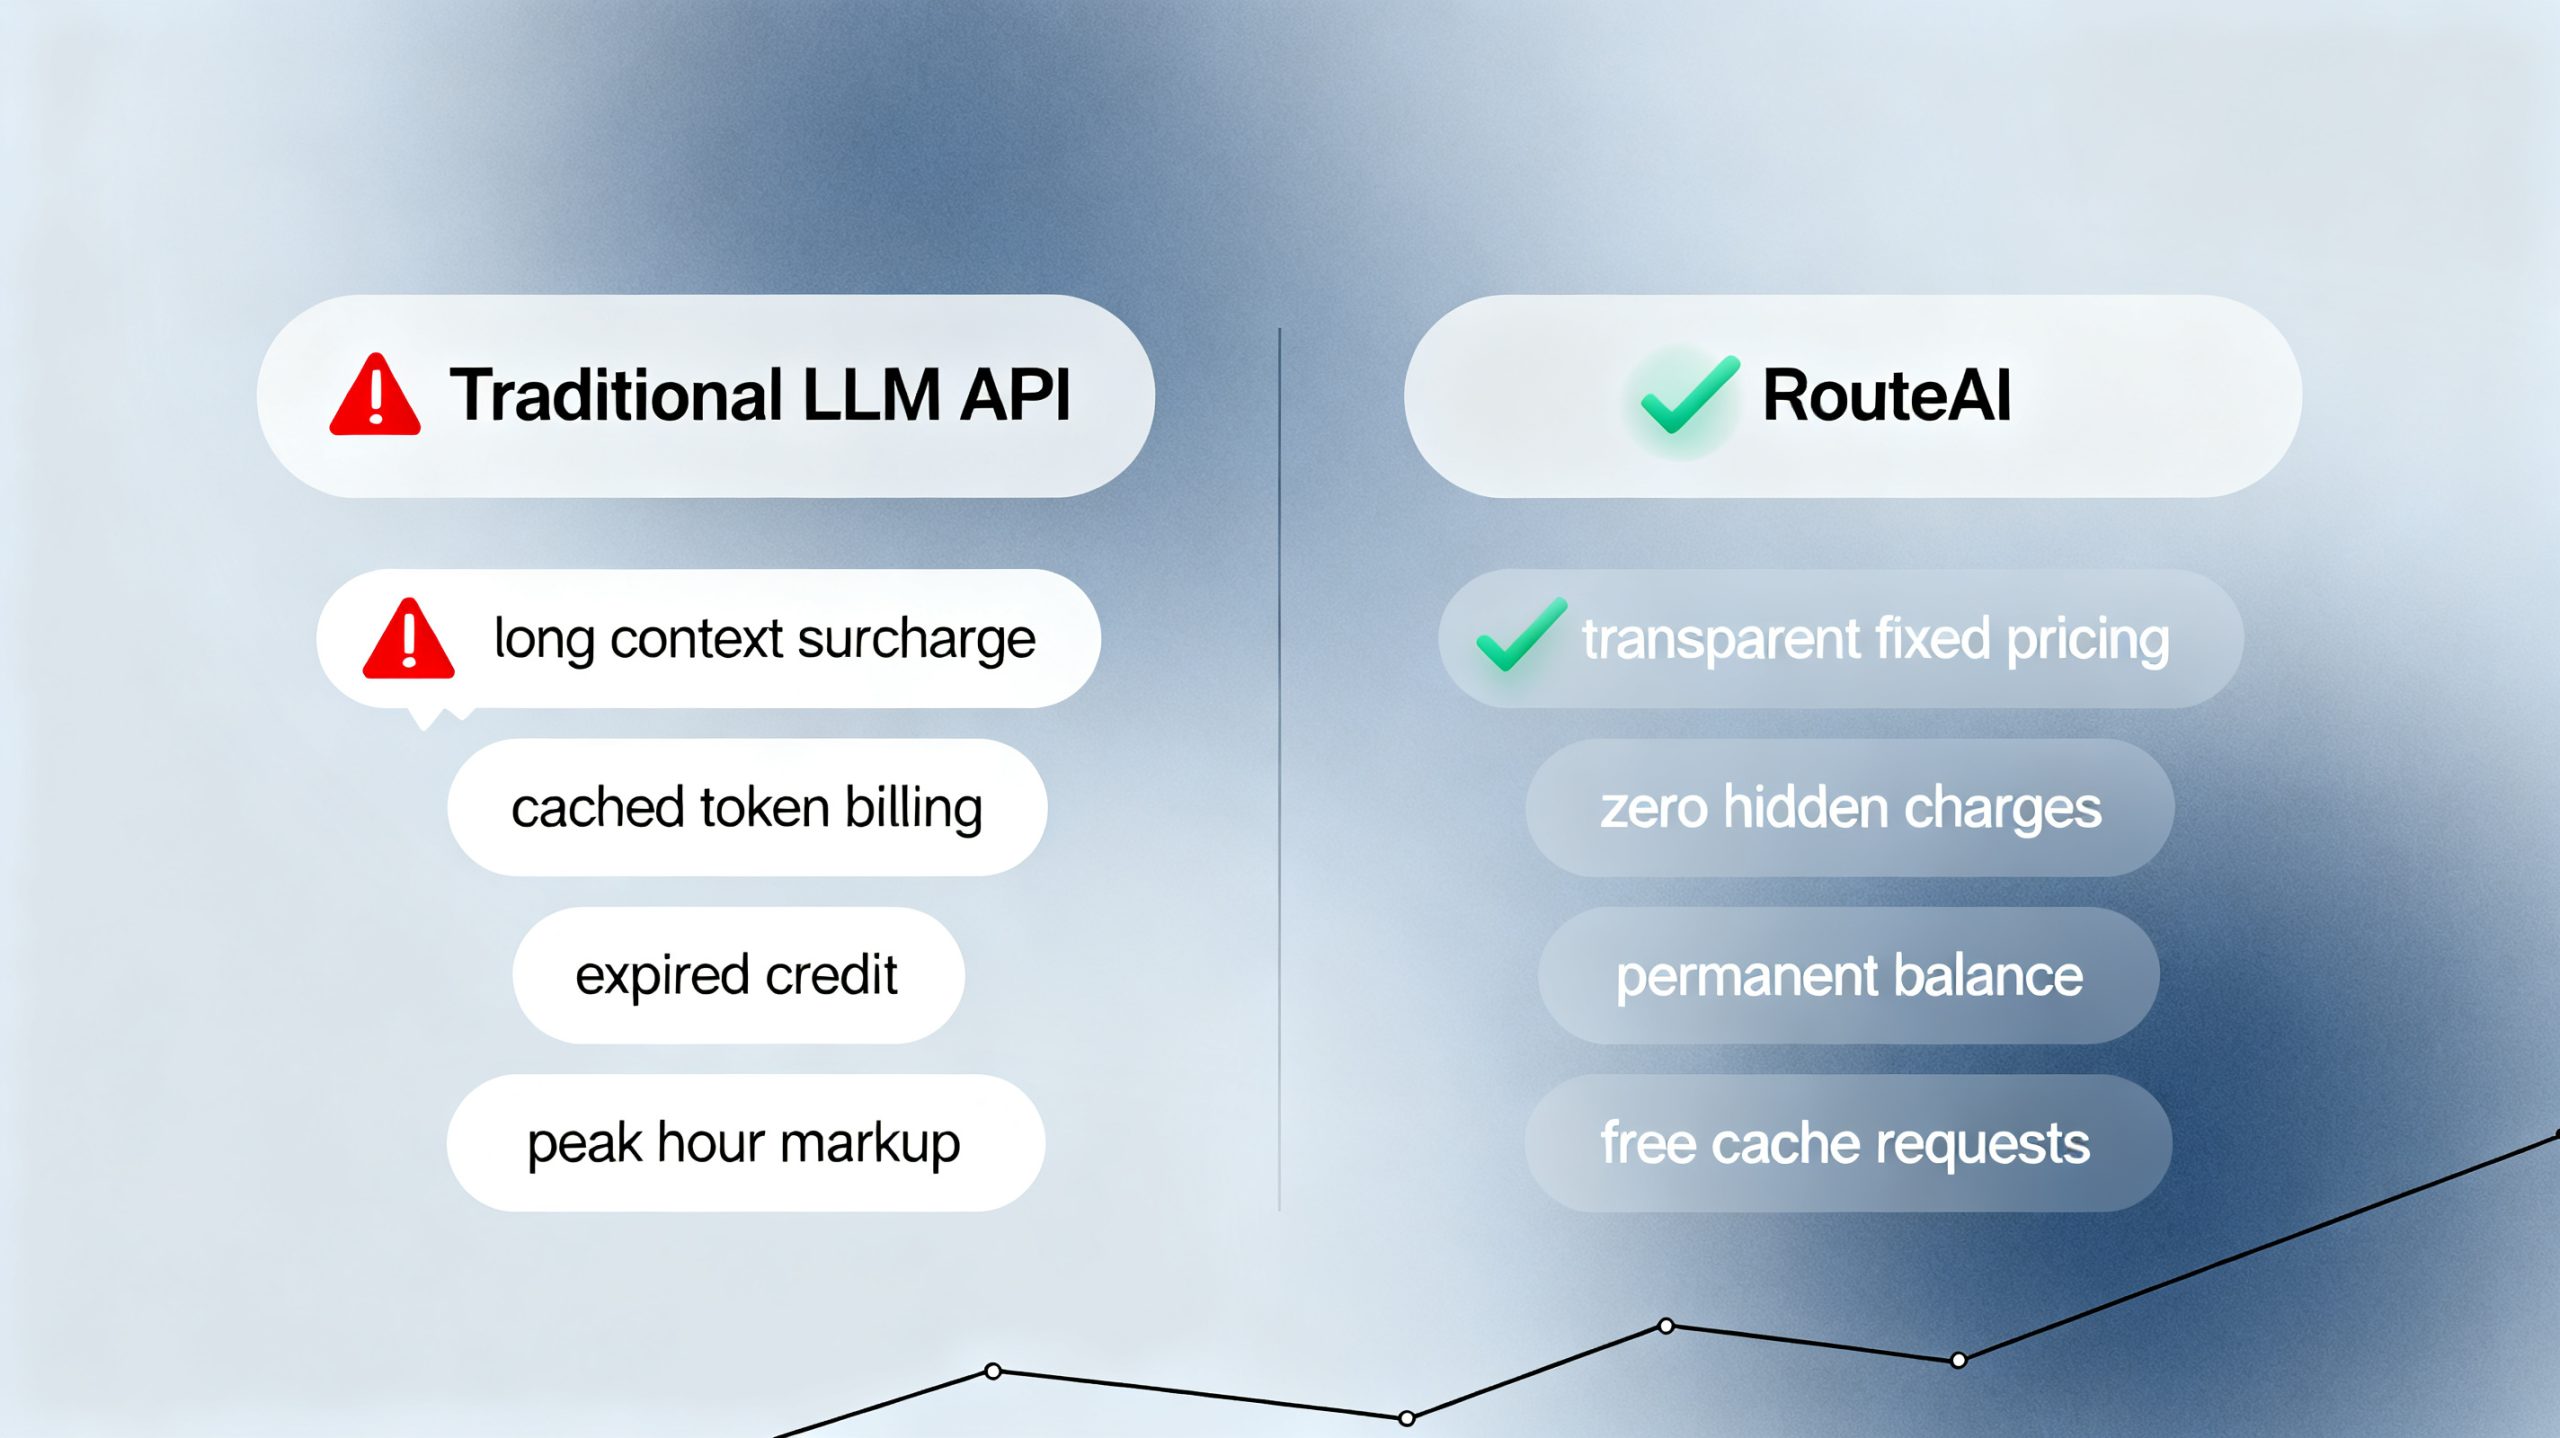
Unexpected overcharges on LLM invoices have become a universal headache for AI developers. Vendors attract users with cheap basic token prices, then stack invisible extra fees that drastically raise your monthly AI budget. Long context window surcharges, billing for cached repeated requests, expired prepaid credits and peak-hour automatic price hikes are four typical hidden traps hurting indie developers and small SaaS teams.
Four Common Hidden Costs Hiding in Standard LLM API Billing
Our 2026 cross-platform price audit covering 15 LLM gateway services identified the most overlooked hidden charges:
- Long context markup: Models with 128k+ context windows add an unadvertised 40% surcharge per request, never displayed on front-page pricing tables.
- Charged cached queries: Duplicate requests hitting server cache still deduct your token quota normally, wasting credits on repeated static prompts.
- Time-limited prepaid balance: Pre-deposited funds expire within 3 to 6 months, with zero refund options for unused leftover balance.
- Peak hour premium pricing: Automatic rate increases activate during US and EU business peak hours without advance notification.
These unpredictable fees make precise financial forecasting impossible. Many small teams are forced to scale down or shut down their AI chatbot and content generation tools entirely due to uncontrollable cost spikes.
RouteAI’s Transparent Billing: Zero Hidden Extra Charges
RouteAI’s core billing framework is built to remove every opaque surcharge found on competing LLM relay platforms. All cost rules are fully public on the official pricing page, with no conditional markup triggered by context length, request frequency or regional traffic time.
1. Uniform token pricing for all context sizes
No extra markup for long context large models like Qwen 2, DeepSeek V4 and GLM. Short prompts and full 128k document inputs share identical per-million-token rates for consistent budgeting.
2. Completely free cached duplicate requests
FAQ templates, repeated customer support queries and frequent test prompts hitting the global cache consume zero tokens. This drastically reduces daily token usage for chatbot and marketing automation projects.
3. Permanent unused credit validity
All prepaid account balance never expires. You can pause your AI project for months or years without losing any deposited funds, eliminating wasted budget from inactive development cycles.
4. Flat global pricing 24/7
Distributed global edge clusters evenly split worldwide traffic load. There are no automatic cost surges during North American or European peak business hours.
Python Script to Track Exact Token Consumption on RouteAI
Every RouteAI API response returns complete token usage data, letting you build custom internal cost tracking tools to avoid unplanned charges:
from openai import OpenAI
client = OpenAI(
    api_key="YOUR_ROUTEAI_API_KEY",
    base_url="https://api.fastrouteai.com/v1"
)
response = client.chat.completions.create(
    model="qwen-3.7-max",
    messages=[{"role": "user", "content": "Write FAQ content for AI SaaS website"}],
    stream=False
)
# Real-time token statistics for cost control
print(f"Input Tokens: {response.usage.prompt_tokens}")
print(f"Output Tokens: {response.usage.completion_tokens}")
print(f"Total Tokens This Request: {response.usage.total_tokens}")
You can log these token metrics to a database for daily, weekly and monthly cost analytics, so you will never face unexplained extra fees on your monthly bill.
Who Saves The Most With RouteAI’s No-Hidden-Fee Pricing
Three types of developers gain the largest cost reduction from transparent LLM billing:
- Hobby creators running low-traffic side AI applications with irregular usage cycles
- E-commerce brands generating daily product descriptions, marketing copy and store chatbot replies
- Early-stage SaaS startups operating fixed-budget customer support AI assistants
Teams previously hit by undisclosed API surcharges can cut their annual AI operating costs by over 50% after switching to RouteAI’s fixed transparent pricing structure.
Stop dealing with unpredictable LLM bill inflation from hidden surcharges. Visit RouteAI’s public pricing page to calculate your accurate monthly AI expenditure with no hidden markup. Enterprise teams seeking volume discounts and dedicated billing dashboards can connect with the official support team via the WhatsApp official channel.
In 2026, predictable, honest pricing should be the industry baseline for production LLM services. RouteAI’s all-in transparent billing lets developers focus on building AI products instead of stressing over surprise monthly cost surges.